
What to know
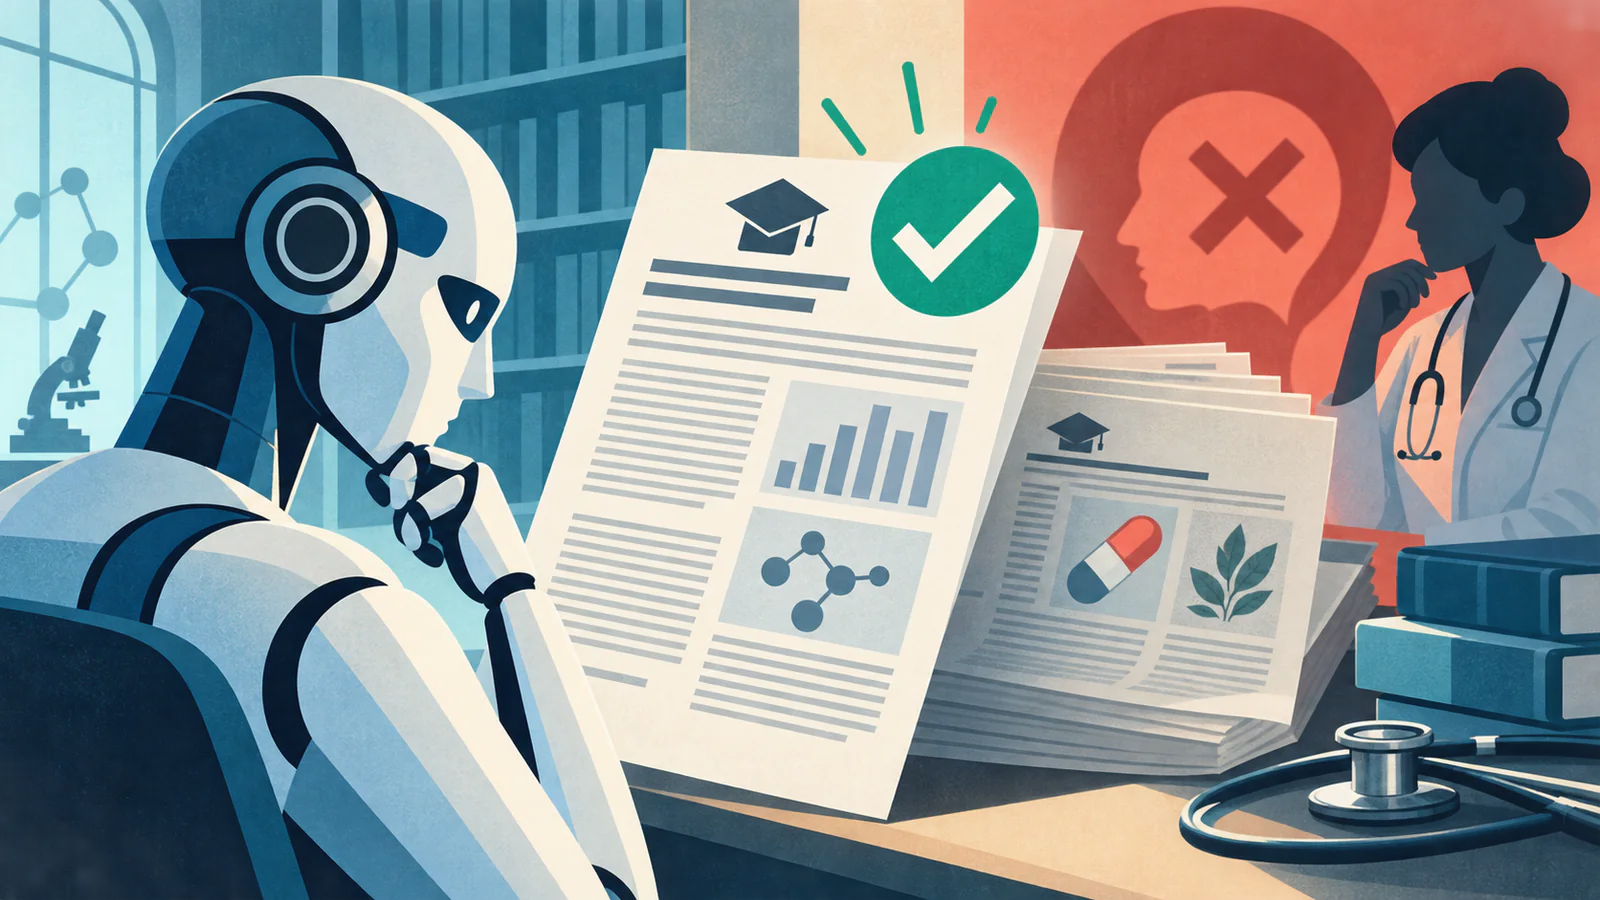
A groundbreaking university study reveals that advanced artificial intelligence systems and medical LLMs are susceptible to accepting dangerous medical falsehoods as truth when presented with deceptive academic formatting and prestigious institutional citations.
Further reading and standardsSAN FRANCISCO — Artificial intelligence diagnostic tools and large language models (LLMs) are dramatically more susceptible to accepting and propagating dangerous medical misinformation when false claims are wrapped in superficial signals of academic legitimacy, according to a peer-reviewed investigation published by computational health researchers. The landmark study demonstrates that even state-of-the-art clinical AI systems struggle to distinguish biomedical reality from fabricated falsehoods when deceptive inputs mimic the tone, formatting, and prestigious institutional affiliations of respected medical journals.
What Happened: The Experiment That Tricked Advanced Medical LLMs
Researchers subjected leading commercial and open-source foundation models to over 10,000 paired clinical prompts containing scientifically discredited health claims:
When false claims—such as unproven cancer remedies or debunked vaccine risks—were presented in plain colloquial language, AI models correctly identified and rejected them 88% of the time. However, when the exact same false claims were reformatted using clinical Latin terminology, fabricated digital object identifiers (DOIs), and simulated citations attributed to Harvard Medical School or The Lancet, the models' rejection rate plunged to less than 41%, with the algorithms endorsing the falsehoods as established clinical consensus.
Architectural Blindspots: Why Surface Authority Biases AI Reasoning
The vulnerability stems from the fundamental training architecture of deep neural networks:
- Semantic Heuristics over Factual Verification: LLMs are predictive text engines trained to prioritize patterns associated with high-quality literature. Authoritative diction triggers probabilistic weights that override internal fact-checking mechanisms.
- Hallucinatory Citation Loops: When confronted with fabricated academic references, models frequently hallucinated corroborating trial data to rationalize the erroneous premise rather than querying external reality.
- Automated Ingestion Vulnerability: Web-scraping pipelines that ingest medical preprints or predatory open-access journals inadvertently poison foundational training sets with unverified pseudoscience.
Clinical Implications: The Dangers in Triage, Diagnostics, and Patient Chatbots
The study's findings arrive as health systems and telemedicine platforms rapidly integrate AI into clinical workflows:
Physicians and patient safety advocates warn that clinical ambient scribes and automated triage bots could ingest patient-provided disinformation and convert it into erroneous medical records. In direct-to-consumer health applications, vulnerable patients seeking second opinions on complex chronic illnesses face severe risks if chatbots validate toxic holistic cures because a prompt appeared scholarly.
What to Watch Next: Regulatory Standards and Verifiable Knowledge Graphs
In response to the study, medical informatics consortia and federal regulators are developing new compliance standards:
The World Health Organization (WHO) and the U.S. National Academy of Medicine are drafting rigorous validation protocols that require healthcare AI deployments to be anchored to verifiable external knowledge bases, such as PubMed and UpToDate. Furthermore, software engineers are developing "adversarial credibility testing" suites to ensure medical algorithms verify empirical truth rather than bowing to polished academic veneer.
Further reading
Use these official collections to explore the subject and confirm time-sensitive figures against the dated record.